Hey. I’m Vlad,

Senior Kubernetes & Platform Engineer

New York, NY Remote or hybrid Open to senior platform roles

I build the platform other engineers ship on — Terraform-managed EKS, GitOps delivery on Argo CD, and policy-as-code guardrails applied to every new application.

Contact me
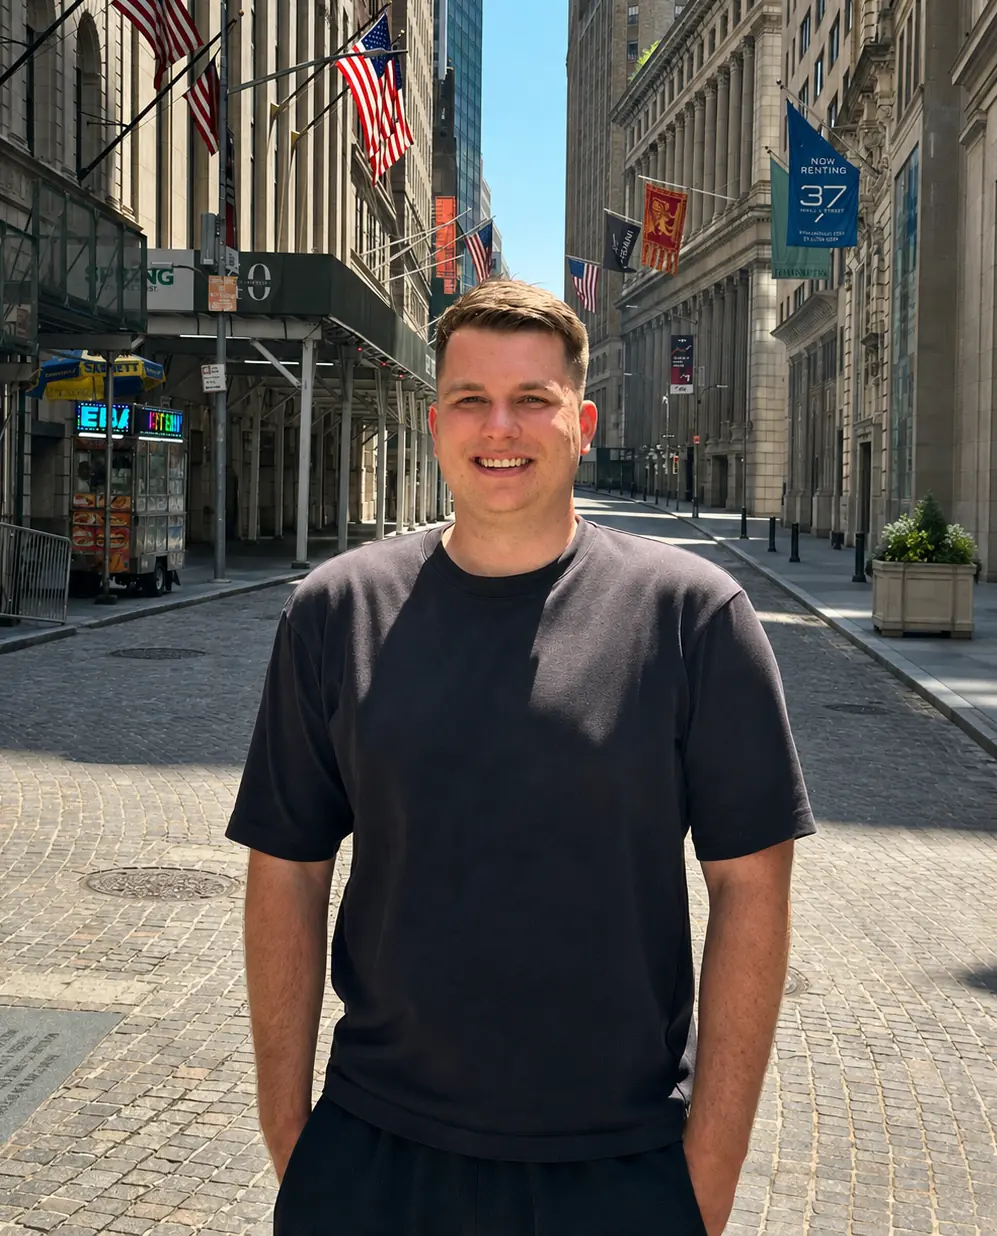
Vlad Mironenko on Wall Street in Lower Manhattan

Skills

  • Kubernetes
  • Amazon EKS
  • Argo CD
  • Flux
  • Kyverno
  • Policy Reporter
  • Karpenter
  • KEDA
  • Helm
  • Terraform
  • AWS
  • EC2
  • VPC
  • IAM
  • S3
  • RDS
  • Lambda
  • Docker
  • Linux
  • OIDC
  • External Secrets Operator
  • Datadog
  • Prometheus
  • Grafana
  • Thanos
  • Alertmanager
  • PagerDuty
  • CloudWatch
  • Python
  • Bash
  • GitHub Actions
  • Claude Code skills
  • MCP servers

Nobody should have to think about the platform

A platform is doing its job when engineers don’t have to think about it. I build infrastructure that makes the path to production predictable — standardized deployments, infrastructure as code, clear ownership, and tooling that removes operational guesswork.

Most of my work is turning one-off processes into systems teams can trust: making deployments consistent, bringing infrastructure under code, simplifying onboarding, and making incidents easier to understand and resolve.

At scale, reliability isn’t about heroic fixes. It’s about removing surprises before they reach production and giving engineers a platform they can use without needing to understand every layer underneath.


Selected Work

ClusterPolicy — require-resource-limits.yaml
apiVersion: kyverno.io/v1
kind: ClusterPolicy
metadata:
  name: require-resource-limits
spec:
  validationFailureAction: Audit   # Enforce once the backlog is drained
  background: true
  rules:
    - name: limits-are-set
      match:
        any: [{ resources: { kinds: [Pod] } }]
      validate:
        message: "CPU and memory limits are required."
        pattern:
          spec:
            containers:
              - resources: { limits: { memory: "?*", cpu: "?*" } }

Policy-as-code across the EKS estate

The hard part wasn’t writing rules, it was landing them on clusters that already had years of running workloads. Every policy shipped in Audit first, so Policy Reporter could show teams their own violations before anything started failing admission — then flipped to Enforce per namespace as each backlog cleared. What a “safe” deployment means stopped being tribal knowledge and became a rule set in git.

Platform
incident-rca — tool trace
$ claude --skill incident-rca --alert "checkout-api p99 latency"

 datadog.query_metrics   read-only   window: -2h
    p99 4.2s ← 380ms baseline, onset 14:07 UTC
 github.list_commits     read-only   repo: checkout-api
    3 merges in window — #2841 "swap connection pool" 14:02
 k8s.get_events          read-only   ns: checkout
    12x Unhealthy — readiness probe timeout

correlation: #2841 precedes onset by 5m · confidence high
# no write-capable tools are registered for this skill

A Claude Code skill for incident RCA

It asks the question an engineer asks first — what changed? — across Datadog, GitHub and the cluster at once, and has an answer before a human finishes opening the dashboards. The design constraint is the interesting part: the MCP servers it talks to expose no write tools at all, so the worst case for a confidently wrong answer is a human wasting two minutes, not an agent mutating production. It shortens investigation; a person still decides.

Agentic
Flux — the Kustomization serving this page
apiVersion: kustomize.toolkit.fluxcd.io/v1
kind: Kustomization
metadata:
  name: vlad-mir-com
  namespace: flux-system
spec:
  interval: 10m
  prune: true          # git is the only way in, and the only way out
  sourceRef: { kind: GitRepository, name: homelab }
  path: ./apps/vlad-mir-com
  images:
    - name: registry.lan/vlad-mir-com
      digest: sha256:9f2c…   # pinned; no mutable tags

A declarative on-prem private cloud

On my own hardware: Harvester HCI underneath, RKE2 guest clusters provisioned from Terraform, everything above them reconciled by Flux. The point of building it was to run the whole loop myself — the parts a managed control plane normally hides. This page is deployed by the manifest above: a digest-pinned image, reconciled from git, with nothing forwarded to serve it.

Homelab

Experience

Epic Games

Senior Infrastructure Engineer

Dec 2023 – Present · Cary, NC

  • Migrated 80+ Kubernetes applications from CI-driven Helm deployments (GitHub Actions) to a pull-based GitOps model on Argo CD, reducing configuration drift across environments.
  • Implemented event-driven autoscaling with KEDA across the platform, reducing cluster compute spend by ~$15K/month by right-sizing capacity to real demand.
  • Standardized 12 EKS clusters with policy-as-code (Kyverno + Policy Reporter), establishing platform-wide deployment standards while surfacing 200+ policy violations across existing workloads.
  • Consolidated legacy AWS infrastructure (IAM, RDS, S3) from CloudFormation to Terraform, importing 40+ previously unmanaged resources into state.
  • Built a Claude Code skill for incident RCA that correlates Datadog telemetry with recent GitHub changes over read-only MCP, cutting investigation time from ~50 min to ~10 min.
  • Consolidated fragmented onboarding docs into a single guide, using it to onboard 4 engineers and reduce ramp-up time for future hires.

Chowly

Cloud Engineer

Oct 2020 – Nov 2023 · Chicago, IL

  • Rolled out Karpenter across 3 EKS clusters, dropping node provisioning time from ~5 min to under 1 min while scaling to 100+ nodes during peak traffic.
  • Extended Prometheus/Grafana with Thanos for global, deduplicated querying across clusters and long-term metric storage — a single source of truth for cross-cluster observability.
  • Automated cleanup of stale EBS snapshots and unused volumes with Python, eliminating idle storage costs and recurring manual maintenance.
  • Served in the 24/7 on-call rotation for production Kubernetes platforms, diagnosing incidents across compute, networking, and deployments.

Education

Master of Science, System Analysis and Management SSU, Krasnoyarsk, Russia
Bachelor of Science, Information and Communication Technology SSU, Krasnoyarsk, Russia

Certifications


Let’s build something

Open to conversations about senior platform and infrastructure roles.

Vlad Mironenko — Senior Infrastructure Engineer · New York, NY Self-hosted on my own platform · deployed from git